Local models (Ollama, LM Studio, llama.cpp)
Run bots on models served from your own computer or network, test them for tool use, and pick them per bot.
Servers Murage knows
Murage looks for these on this computer by itself:
- Ollama at
127.0.0.1:11434 - LM Studio at
127.0.0.1:1234 - llama.cpp at
127.0.0.1:8080 - vLLM at
127.0.0.1:8000 - SGLang at
127.0.0.1:30000 - EXO at
127.0.0.1:52415 - Unsloth at
127.0.0.1:8888
oMLX and any other server with an OpenAI-style API can be added by address.
Set it up
Step 1
Start your model server
Start your model server and load a model.
You're done when: the server is running with a model loaded.
Step 2
Open Local models
Open SettingsModelsLocal models. Murage says Checking this computer for model servers… and then lists what it found, with Running or Not answering for each server.
If your server is on another machine, choose Add a server. Pick the Server type (or Detect automatically), give it a Server name (optional), enter the Server address, and add a Server API key (optional) only if the server needs one. Choose Add server.
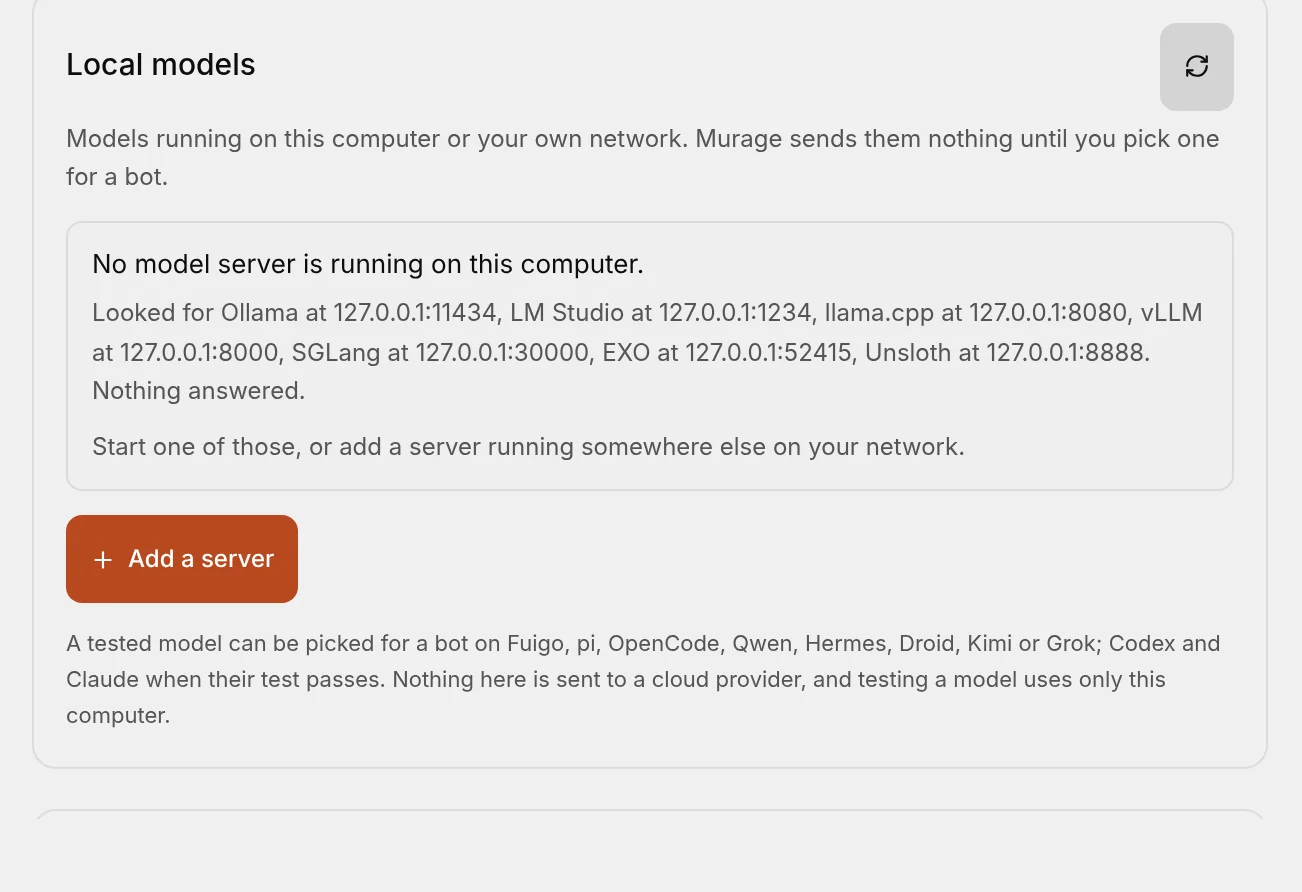
You're done when: your server is listed as Running.
Step 3
Test the model
Next to a model, choose Test. The test runs seven checks on this computer. No cloud provider is called and nothing is billed.
You're done when: it says Tools work - ready for bots.
Step 4
Use it with a bot
Choose Use with a bot. The model menu of every open bot now shows it.
Then open a bot, go to Bot settingsModel and pick the model. It's listed under the local models group with its server's name.
You're done when: the bot shows your local model.
Addresses on this computer, your home network or your tailnet can be plain http. Anything else has to be https. A saved key is stored on this computer and is only ever sent to that address.
What the test checks
- Calls a tool when told to
- Calls a tool when it should
- Streams tool calls
- Uses a tool result
- Handles a full tool set
- Responses-style tools (Codex)
- Anthropic-style tools (Claude)
The result tells you which engines can use the model, for example "Usable by Fuigo, pi, OpenCode".
Which engines can use a local model
- Fuigo, pi, OpenCode, Qwen, Hermes, Droid, Kimi and Grok Build: any local model that answers.
- Codex: only after the model passes Responses-style tools (Codex).
- Claude Code: only after the model passes Anthropic-style tools (Claude).
- OpenAI-compatible: any local model. It uses your bot's tools; a model that can't take tools still chats.
- Google Antigravity and Cursor: can't use local models.
Each engine's row in SettingsModels & enginesEngines says where it stands, for example "Works with local models - manage them under Models > Local models".
When you pick a local model on Kimi, Qwen, Hermes, OpenCode, pi or Grok Build, Murage adds a small entry for that server to the engine's own settings so the engine can reach it. If you change a server's address or key, Murage removes the entries it wrote, and the next turn writes fresh ones.
Context size
Bots need room to work. Murage asks for at least 32K tokens of context and recommends 64K.
- If the model is loaded with less, the test says Context too small for bots.
- On Ollama, choose Create a 64K copy. Murage makes a copy of the model with a larger context on your Ollama server. The original is untouched. Test the copy.
- On other servers, restart the server with a larger context setting.
Known limits
- Small models are slower. Small local models are slower and less reliable than hosted ones, especially with many tools.
- Nothing is sent early. Murage sends a local model nothing until you pick it for a bot.
- Some things still use outside services. Voice, web search and connected apps still use Flux Router or your own keys.
Troubleshooting
You see
No model server is running on this computer.Do this
Start Ollama, LM Studio or another server, then choose Check again. Or add a server that runs elsewhere on your network.
You see
Nothing answered at this address. Start the server, then check again.Do this
Check the address and port, and that the server is listening on your network, not only on its own machine.
You see
This server answered but listed no model Murage can address.Do this
Load a model on the server, then check again.
You see
This model answers but can't use tools (it came back as text)Do this
Pick another model and test it, or use this one on the OpenAI-compatible engine for plain chat.
You see
This server rejects tools - it has to be started with them enabledDo this
Choose Copy the fix to copy the setting to start the server with, such as --jinja for llama.cpp, restart the server and test again.
You see
Tools work, with gaps - some agent behavior may be unreliableDo this
It will work for simple jobs. For more demanding bots, try a larger model.
You see
No engine can use this model yet - run the test firstDo this
Choose Test next to the model.